List:
Functional Programming Principles in Scala – Martin Odersky
main programing paradigms:
- imperative programming: modify mutable variables, using assignments, control structures such as if else etc
- functional programming: in a restricted sense, a FP language is one which does not have mutable variables, assignments or imperative control structures; in a wider sense, a FP language enables the construction of elegant programs that focus on functions. Functions can be defined anywhere including inside other functions. Functions can be passed as parameters to functions and returned as results. There are a set of operators to compose functions.
- logic programming
- object-oriented programming (orthogonal to above 3)
FP evaluation strategy
-
call by value: not lazy, reduces variable first and then evaluate (x:Int), default use of scala
sumOfSqures(3, 2+2) sumOfSqures(3,4) squre(3) + squre(4) 3*3 + square(4) 9 + square(4) 9 + 4*4 9 + 16 25 -
call by name: lazy evaluation, evaluate first and then reduce (x: => Int), less efficient than CBV
 sumOfSqures(3, 2+2)
 square(3) + square(2+2)
 3*3 + squre(2+2)
 9 + square(2+2)
 9 + (2+2) * (2+2)
 9 + 4 * (2+2)
 9 + 4 * 4
 25
conditions and value definitions
- def is like CBN, its right hand side is evaluated only when it is used
-
val is like CBV, its right hand side is evaluated immediately Implement and(x,y)
 Def and(x: Boolean, y:=> Boolean) = {
   if (x) y
   else false
 }

 Notice that y is CBN because if we call (false, loop), the CBV version will go into infinite loop
square roots with Newton’s method
A typical way to code algorithms in FP is to go step by step. So we take a small task and formulate it as a function and then probably that task will need further tasks that would be defined in their own function.
For instance, to implement the square function using Newton’s method, we can sketch as follows:
def sqrtIter(guess: Double, x: Double): Double = {
  if (isGoodEnough(guess, x)) guess
  else sqrtIter(improve(guess,x), x)
}

and then we can continue to fill isGoodEnough and improve
side note: recursive functions need an explicit return type in scala (: Double in sqrtIter) in scala. For non-recursive functions, the return type is optional
Tail recursion
If a function calls itself as its last action, the function’s stack frame can be reused. This is called tail recursion. Tail recursive functions are iterative processes. Broadly speaking, if the last action of a function consists of calling a function (which may be the same), one stack fram would be sufficient for both functions. Such calls are called tail calls.
def gcd(a: Int, b: Int): Int = {
  if (b==0) a
  else gcd(b, a%b)
}
this is tail recursion.

Factorial is not tail recursion, because besieds calling itself, it also multiply a number: factorial(n) = n*factorial(n-1)
Higher-order functions
Functions that take other functions as parameters or that return functions as results are called higher order functions. For example, write a general sum function (take function as parameter)
def sum(f: Int=>Int, a: Int, b: Int): Int = {
  if (a>b) 0
  else f(a) + sum(f, a+1, b)
}

we can then write:
def sumInts(a: Int, b: Int) = sum(id, a, b) where def id(x: Int): Int = x
def sumCubes(a: Int, b:Int) = sum(cube, a, b) where def cube(x: Int): Int = x*x*x
def sumFactorials(a: Int, b: Int) = sum(fact, a, b) where def fact(x: Int): Int = if(x==0) 1 else x*fact(x-1)
Anonymous function:
e.g. (x: Int) => x*x*x     (x: Int, y: Int) => x+y
Here (x: Int) is the parameter of the funciton and x*x*x is its body
The type of the parameter can be omitted if it can be inferred by the compiler from the context
It is a syntactic sugar which makes writing easier
An anonymous function (x1: T1, ... , xn: Tn) => E can always be writen as:
def f(x1: T1,..., xn: Tn) = E; f

So with anonymous function, the sum function above can be rewritten as:
def sumInts(a: Int, b: Int) = sum(x=>x, a, b)
def sumCubes(a: Int, b:Int) = sum(x=>x*x*x, a, b)
Currying
Currying means defining functions parameters piecewise, one parameter section after the other. The benefit is: - less parameters to worry about when you have implicit parameters - allow you to pass anonymous function to a method
  The previous example sumInts, sumCubes, sumFactorials need to pass in a, b always. We can make the code shorter by getting rid of these parameters:

  def sum(f: Int => Int): (Int, Int) => Int = {
    def sumF(a: Int, b: Int): Int = {
      if (a>b) 0
      else f(a) + sumF(a+1, b)
    }
    sumF
  }

  so sum now is a function that returns another function

  we can define the above functions as:
  def sumInts = sum(x => x)
  def sumCubes = sum (x => x*x*x)
  def sumFactorials = sum(fact)

  to use it, we can do sumInts(1,10),   sumFactorials(10,20) . Notice, now we pass in the parameter to the inner function sumF, which is the return type of sum

  or we can use as a whole: sum(cube)(1,10) insteading of writing separately
An easier way to write sum (with inner function sumF) is as follows:
  def sum(f: Int => Int)(a: Int, b: Int): Int =
    if (a>b) 0 else f(a) + sum(f)(a+1,b)

  side note: The type of sum is (Int => Int) => ((Int, Int) => Int)
The idea here is that:
   if we have def f(args1)...(argsn) = E
   it is equivalent to def = (args1 => (args2 => ... (argsn => E) ...))
   so in terms of the sum function above, if I call sum(f), then it returns another function which is (a,b) => Int (where E = Int in this case)
   This is the beauty of carrying!
An interesting exercise: to write a map reduce and write product in the mapreduce form:
    // the f:Int=>Int is like a map and combine is a reduce
    // so the idea is to map one element a time and then do the reduce
    def mapReduce(f:Int=>Int, combine:(Int,Int)=>Int,zero:Int)(a:Int,b:Int):Int =
      if( a>b ) zero
      else combine(f(a),mapReduce(f,combine,zero)(a+1,b))

    // we specify the reduce as multiplication two values together
    def product(f:Int=>Int)(a:Int,b:Int):Int= mapReduce(f,(x,y)=>(x*y),1)(a,b))
fixed point
a number is called a fixed point of a function if f(x) = x for some functions we can locate the fixed points by starting with an initial estimate and the apply f in a repetitive way (f(f(x)…) sqrt can be computed using fixed point. sqrt(x) = y => y*y = x => y = x/y => f(y) = x/y for fixed x which matches the fixed point definition. We can code as follows:
  val tolerance = 0.0001
  def isCloseEnough(x: Double, y: Double) = abs((x-y)/x)/x < tolerance
  def fixedPoint(f: Double => Double)(firstGuess: Double) = {
    def iterate(guess: Double): Double = {
      val next = f(guess)
      if (isCloseEnough(guess,next)) next
      else iterate(next)
    }
    iterate(firstGuess)
  }
  def sqrt(x: Double) = fixedPoint(y => x/y)(1.0)

  but in this way, the program does not converge.
  Use the idea of average damping which is to average the result we get in every iteration. So we change the pass in function f as follows:
  def sqrt(x: Double) = fixedPoint(y => (y+x/y)/2)(1.0)
Function and data
class which defines a new type and a constructor (the type can be passed in as argument). For example:
  class Rational(x: Int, y: Int) {
    def numer = x
    def denom = y
  }

  to create an object:
  we can use **new Rational(1,2)**
  or we can do:

  object rationals {
    val x = new Rational(1,2)
    x.number
    x.denom
  }
We can also implement our own way of adding rational:
    class Rational(x: Int, y: Int) {
      // gcd is computed immediately so that its value can be re-used
      private def gcd(a: Int, b: Int): Int = if (b==0) a else gcd(b, a%b)
      private val g = gcd(x,y)
      def number = x/g
      def denom = y/g

      def add(that: Rational) = new Rational(number*that.denom + that.number*denom, denom*that.denom)

      override def toString = number + "/" + denom
    }
- Data abstraction: the ability to choose different implementations of the data without affecting clients
- Assert and precondition (require):
- assert is used as to check the code of the function itself
- require is used to enforce a precondition on the caller of a function
-
create constructor inside a class:
class Rational(x: Int, y: Int) { require(y!=0, "denominator must be nonzero") def this(x: Int) = this(x,1) // create a constructor } -
operators: We can define (override) custom +,-,*,/ etc in a class
  def + (that Rational) = new Rational(number * that.denom + that.number * denom, denom * that.denom)

  def - (that: Rational) = this + that.neg

  def < (that: Rational) = number * that.denom < that.numer * denom
Class Hierarchies
-
abstract class can contain members which are missing an implementation; no instance can be created with keyword “new”
abstract class IntSet { def incl(x: Int): IntSet def contains(x: Int): Boolean } -
override: redefine an existing, non-abstract definition in a subclass
abstract class Base { def foo = 1 def bar: Int } class Sub extends Base { override def foo = 2 def bar = 3 } - object class defines a singleton class, no other instances can be created
- dynamic binding:
- the code invoked by a method call depends on the runtime type of the object that contains the method
-
packages: classes and objects are organized in packages
package progfun.examples object Hello {...} The Hello can be refered by: progfun.examples.Hello - traits: classes, objects and traits can inherit from at most one class but arbitrary many traits
- trait is similar to interface in Java but can contain both fields and concrete methods
-
trait cannot have value parameters, only class can
trait Planar {
  def height: Int
  def width: Int
  def surface = height * width
}

to extend trait, we can use keyword "extends" (for the first extension) and "with" (for the rest extension)
class Square extends Shape with Planar with Movable
Types in Scala
- Any: the base type of all types
- AnyRef: The base type of all reference types
- AnyVal: The base type of all primitive types
- Nothing: At the bottom of scala’s type hierarchy. It is a subtype of every other type. It is used to signal abnormal termination and as an element type of empty collections.
- null: it is a subtype of every class that inherits from Object; it is incompatible with subtypes of AnyVal
The types hierarchy is seen as follows:
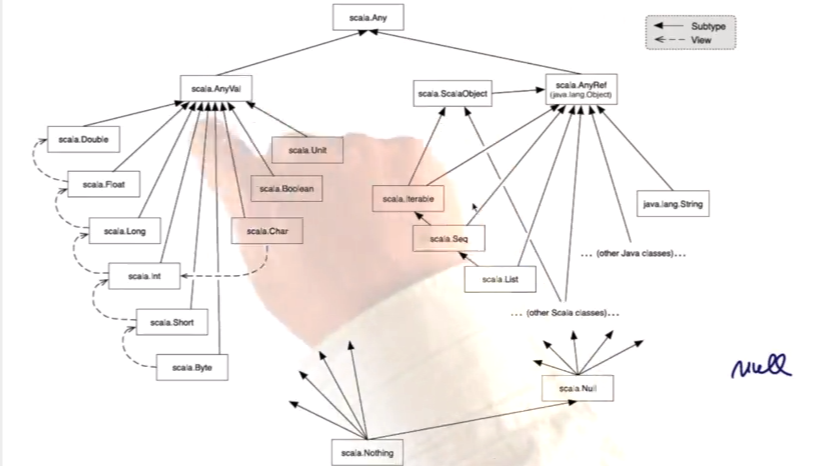
-
generic types: type parameters written in square brackets ([T])
trait List[T] class Cons[T](val head: T, val tail: List[T]) extends List[T] class Nil[T] extends List[T] - type erasure: all type parameters and type arguments are removed before evaluating the program. To keep the type, we can use ClassTag or TypeTag (here)
- polymorphism: it means that a function type comes “in many forms”:
- the function can be applied to arguments of many types
- the type can have instances of many types
- two principals:
- subtyping: instances of a subclass can be passed to a base class (comes from O-O)
- generics: instances of a function or class are created by type parameterization (comes from FP)
-
type bounds:
S <: T: S is a subtype of T (S points to T in the hierarchy diagram)
S >: T: S is a supertype of T
mixed bound: [S >: NonEmpty <: IntSet] // it is possible to mix a lower bound with an upper bound, it restricts S to be any type between NonEmpty and IntSet
Functions as Objects
  The function type A=>B is just an abbreviation for the class scala.Function1[A,B] which is defined as follows:
  trait Function1[A,B] {
    def apply(x: A): B
  }
Therefore functions are objects with apply methods
Covariance
The defintion is as follows:
  Given NonEmpty <: IntSet
  if List[NonEmpty] <: List[IntSet] then we say list is covariant
Immutable type is covariant. So list is covariant but array is not covariant
-
variance:
Say C[T] is a parameterized type and A,B are types such that A <: B There are three possible relationships between C[A] and C[B]: C[A] <: C[B] -> C is covariant C[A] >: C[B] -> C is contravariant neither C[A] nor C[B] is a subtype of the other -> C is nonvariant -
Scala lets you declare the variance of a type by annotating the type parameter:
class C[+A] {...} -> C is covariant class C[-A] {...} -> C is contravariant class C[A] {...} -> C is nonvariant -
typing rules for functions
If A2 <: A1 and B1 <: B2, then A1 => B1 <: A2 => B2 -
function trait declaration: functions are contravariant in their arguments type(s) and covariant in their result type
trait Function1[-T, +U] {
  def apply(x: T): U
}
the compailer of Scala needs to make sure: - covariant type parameters can only appear in method results - contravariant type parameters can only appear in method parameters - invariant type parameters can appear anywhere
Pattern match
-
case classes: similar to normal class defintion except that it is preceded by the modifier case
trait Expr case class Number(n: Int) extends Expr it is also implicitly defines companion objects with apply methods: object Number { def apply(n: Int) = new Number(n) } so we can call Number(2) which is equivalent to Number.apply(2) -
pattern match is a generalization of switch from C/Java to class hierarchies
As an example: def eval(e: Expr): Int = e match { case Number(n) => n case Sum(e1, e2) => eval(e1) + eval(e2) } - match syntax: match is followed by a sequence of cases, pat => expr
- forms of patterns:
- constructors such as Number, Sum
- variables such as n, e1, e2
- wildcard patterns “_”
- constants such as 1, true
- the same variable name can only appear once in a pattern, so sum(x,x) is not a legal pattern
List methods
- xs.length: get the length of list xs
- xs.last: return xs’s last element. Exception if xs is empty
- xs.init: return a list containing all elements of xs except the last one. Exception if xs is empty
- xs take n: return a list containing n prefix of xs or xs it self if it is shorter than n
- xs drop n: return the rest of the collection after taking n elememts
- xs(n): the elememt of xs at index n
- xs ++ ys: return the list consisting of all elements of xs followed by all elements of ys
- xs.reverse: the list containing all elements of xs in reversed order
- xs updated (n,x): return a new list that contain the same elements as xs, except at index n where it contains x
- xs indexOf x: the index of the first element in xs equal to x or -1 if x does not appear in xs
-
xs contains x: same as xs indexOf x >=0
The implementation of init, concat, reverse:

def init[T](xs: List[T]): List[T] = xs match {
  case List() => throw new Error("init of empty list")
  case List(x) => List()
  case y::ys => y::init(ys)
}

def concat[T](xs: List[T], ys: List[T]) = xs match {
  case List() => ys
  case z::zs => z::concat(zs,ys)
}

// O(n^2) n to iterator, n to concat. Can do better
def reverse[T](xs: List[T]): List[T] = xs match {
  case List() => xs
  case y::ys => reverse(ys) ++ List(y) // use ++ because :: use for element and then list, no the reverse way
}
Pair and tuples
  val pair = ("answer", 42) // how to create pair
  val (label, value) = pair // how to receive pair
The above works analogously for tuples with more than two elements
Mergesort:
  def merge(xs: List[Int], ys: List[Int]): List[Int] = {
    (xs, ys) match {
      case (Nil, ys) => ys
      case (xs, Nil) => xs
      case (x :: xs1, y :: ys1) => {
        if (x<y) x::merge(xs1,ys)
        else y::merge(xs, ys1)
      }
    }
  }

  def msort(xs: List[Int]): List[Int] = {
    val n = xs.length/2
    if (n==0) xs
    else {
      val (fst, snd) = xs splitAt n
      merge(msort(fst, msort(snd))
    }
  }

  // my own implementation, not shown in the course material and not been fully tested
  def splitAt(x: List[Int]): (List[Int], List[Int]) = {
    (x.take(n), x.drop(n))
  }
implicit parameters
Follow the above example, how can we parametrerize msort so that it can also be sued for lists with elements other than Int?
def msort[T](xs: List[T]): List[T] = ...
does not work because comparison < in merge is not defined for arbitrary types T
The idea is to parameterize merge with the necessary comparison function:
  def msort[T](xs: List[T])(lt: (T,T)=>Boolean): List[T] = ...
  so the < comparison in merge can be replaced by lt(x,y)

  There is also a class in scala (scala.math.Ordering[T]) that can compare elements of type T. So we can directly parameterize with lt operation directly: def msort[T](xs: List[T])(ord: Ordering): List[T] = ...
  we can use ord.lt(x,y) in replace of the < comparison

  when we call it, we can do msort(nums)(Ordering.Int)
To avoid passing lt or ord all the time, make it implicit so that compiler will figure out the right implicit to pass based on the demanded type
  def msort[T](xs: List[T])(implicit ord: Ordering): List[T] = ...
  now when we call it, we only need to do msort(nums)
Say a function takes an implicit parameter of type T, the compiler will search an implicit definition that: - is marked implicit - has a type compatible with T - is visible at the point of the function call or is defined in a companion object associated with T If there is a single definition, it will be taken as actual argument for the implicit parameter Otherwise, it is an error
Higher-order list functions
used to write generic functions that implement patterns such as: - transforming each element in a list in a certain way - retrieving a list of all elements satisfying a criterion - combining the elements of a list using an operator For example, we can write a simplified map as:
  abstract class List[T] {
    def map[U](f: T=>U): List[U] = this match {
      case Nil => this
      case x::xs => f(x) :: xs.map(f)
    }
  }

  Using map, scaleList can be written as:
  def scaleList(xs: List[Double], factor: Double) = {
    xs map (x => x*factor)
  }
filter can be defined as follows:
  abstract class List[T] {
    def filter(p: T => Boolean): List[T] = this match {
      case Nil => this
      case x::xs => if (p(x)) x :: xs.filter(p) else xs.filter(p)
    }
  }
variations of Filter: xs filterNot p: keep the complemet of xs filter p xs partition p: create a pair which contains (xs filter p, xs filterNot p) xs takeWhile p: the longest prefix of list xs consisting of elements that all satisfy the predicate p xs dropWhile p: the remainder of the list xs after any leading elements satisfying p have been removed (complement of takeWhile) xs span p: create a pair (xs takeWhile p, xs dropWhile p)
Notice span stops and won’t go all the way through the list if p is satisfied, but filter goes through the whole list
Exercise: write a function that packs consective duplicates of list elements into sublists. For instance, pack(List(‘a’,’a’,’b’)) gives List(List(‘a’,’a’), List(‘b’))
  def pack[T](xs: List[T]): List[List[T]] = xs match {
    case Nil => Nil
    case x::xs1 => {
      val (first, rest) = xs span (y => y==x)
      first :: pack(rest)
    }
  }
Exercise: write a function that packs consective duplicates of list elements into sublists. For instance, pack(List(‘a’,’a’,’b’)) gives List(List(‘a’,2), List(‘b’,1))
  def encode[T](xs: List[T]): List[(T, Int)] = xs match {
    pack(xs) map (ys => (ys.head, ys.length))
  }
Reduction of Lists
The purpose is to combine the elements of a list using a given operator
reduceLeft: inserts a given binary operator between adjacent elements of a list
  def sum(xs: List[Int]) = (0::xs) reduceLeft((x,y) => x + y)
  def product(xs: List[Int]) = (1::xs) reduceLeft((x,y) => x*y)
A shorter way to write is:
  def sum(xs: List[Int]) = (0::xs) reduceLeft(_+_)  // every _ represents a new paramter. The parameter is defined (implicitly) at the next outer pair of parentheses
  def product(xs: List[Int]) = (1::xs) reduceLeft(_*_)
foldLeft: similar to reduceLeft but takes an extra accumulator which is returned if foldLeft is called on an empty list
  def sum(xs: List[Int]) = (xs foldLeft 0) (_+_)
  def product(xs: List[Int]) = (xs foldLeft 1) (_*_)
Similarly, there is also reduceRight and foldRight which unfold o trees that lean to the left For operators that are associative and commutative, foldLeft and foldRight are equivalent
Some proof knowledge
- structural induction: to prove a proerpty P(xs) for all lists xs, show that P(Nil) holds (base case), for a list xs and some element x, show the induction step: assume P(xs) holds, then P(x::xs) also holds
Other collections
- vector: it has more evenly balanced access patterns than List. If the length is less than 32, then it is an array. If larger it has 2 levels of storage (like file system learned in CS110), so it can store at most 3232 = 210 elements so on and so forth. The time to access a number is log 32 (N). It is good for traversing (bulk operation).
-
usage:
val nums = Vector(1,2,3)

// it supports same operations as lists except ::
// instead of x :: xs, there is:
x +: xs: create a new vector with leading element x followed by all elements of xs
xs :+ x: create a new vector with trailing element x, preceded by all elements of xs

in general: ":" always point to the sequence
-
- list, vector are base class of Seq; seq, set, map are base class of iterable
-
arrays and strings support the same operation as Seq and can implicitly be converted to sequences where needed
val xs: Array[Int] = Array(1,2,3) xs map (x => 2*x) val ys: String = "Hello World!" ys filter (_.isUpper) -
Ranges: represented as single objects with three fields (lower bound, upper bound, step value)
var r: Range = 1 until 5 // 1,2,3,4 var s: Range = 1 to 5 // 1,2,3,4,5 1 to 10 by 3 // 1,4,7,10 6 to 1 by -2 // 6,4,2 - sequence operations
- xs exists p: check if p exists in xs
- xs forall p: true if p(x) holds for all elements x of xs
- a zip b: generate a list of pairs drawn from corresponding elements of sequences a and b
- xs.unzip: splits a list of pairs xs into two sequences consisting of the first and second halves of all pairs
- xs.flatMap f
- xs.sum: the sum of all elements of this numberic collection
- xs.product
- xs.max
- xs.min
Combinatorial search and for-expressions
-
generate the sequence of all pairs of integers (i,j) such that 1<=j<i<n
(1 until n) map (i=> (1 until i) map (j => (i,j)) // this generates a vector of vector -
to genreate a vector of pair, we can do:
((1 until n) map (i=> (1 until i) map (j => (i,j))).flatten or (1 until n) flatMap (i=> (1 until i) map (j => (i,j)) or for { i <- 1 until n j <- 1 until i if isPrime(i+j) } yield (i,j) -
for comprehension: it is similar to loops in imperative languages except that it builds a list of the results of all iterations. It is of the form: for (s) yield e
- s is a sequence of generators and filters
- a generator is of the form p <- e where p is a pattern and e an expression whose value is a collection
- a filter is of the form if f where f is a boolean expression
- the sequence must start with a generator
-
e is an expresson whose value is returned by an iteration
case class Person(name: String, age: Int)
to obtain the names of persons over 20 years old, we can do:
for (p <- persons if p.age>20) yield p.name
it is equivalent to: persons filter (p => p.age > 20) map (p=>p.name)
- s is a sequence of generators and filters
Combinational Search Example
-
sets: basic abstraction in scala collections
val fruit = Set("apple", "banana", "pear") val s = (1 to 6).toSet - sets vs sequences:
- sets are unordered
- sets do not have duplicate elements
- the fundamental operation on sets is contains
-
Nqueens example
def queens(n: Int): Set[List[Int]] = {
  def placeQueens(k: Int): Set[List[Int]] = {
    if (k==0) Set(List())
    else
      for {
        // get the result from last step, each result is of type: List[Int]
        queens <- placeQueens(k-1)
        // loop all the places that could place a queen
        col <- 0 until n
        if isSafe(col, queens)
      } yield col :: queens
  }
  placeQueens(n)
}
def isSafe(col: Int, queens: List[Int]): Boolean = {
  val row = queens.length
  // we model the solution by giving a list of columns and in the order of last row to first row
  // so here we just need to get the (row, col) pair for each valid queen
  val queensWithRow = (row - 1 to 0 by -1) zip queens
  queensWithRow forall {
    // the second condition is to avoid two queens in the same diagonal
    case (r,c) => col != c && math.abs(col-c) != row - r
  }
}
Maps
  val romanNumerals: Map[String, Int] = Map('I'->1, 'V'->5)
  val capitalOfCountry: Map[String,String] = Map("US"->"Washington")
Maps can be iterable, maps can also be functions\
- option type which is map get key returns
- None if map does not contain the given key
- Some(x) if map associates the given key with the value x
- orderBy on a collection can be expressed by sortWith (receive a predicate as a parameter) and sorted
- groupBy: partitions a collection into a map of collections according to a discriminator function f
- withDefaultValue: use the default value if the key is not in the map to avoid exception